Cloudflare | 2025-11-18T00:00:00Z
A root cause analysis of Cloudflare's November 2025 outage, where a database permissions change produced an oversized Bot Management feature file and disrupted core traffic handling.
AWS | 2025-10-19T00:00:00Z
A production incident case study of the October 2025 AWS US-EAST-1 outage, where a DynamoDB DNS automation race condition cascaded into EC2, NLB, Lambda, and other services.
Google Cloud | 2025-06-12T00:00:00Z
A root cause analysis of Google Cloud's June 2025 outage, where a Service Control quota policy path crashed globally after invalid policy data propagated within seconds.
CrowdStrike | 2024-07-19T00:00:00Z
A production incident case study of CrowdStrike's July 2024 Falcon content update, which caused widespread Windows crashes and long manual recovery for affected machines.
Reddit | 2023-03-14T00:00:00Z
Explore Reddit's 314-minute Pi Day outage in 2023, the Kubernetes label change behind the routing failure, and an exercise for uncovering hidden dependencies.
Cloudflare | 2022-06-21T00:00:00Z
What caused Cloudflare's June 2022 outage? Learn how a routing policy change affected 19 locations and how to design a more representative rollout exercise.
Atlassian | 2022-04-05T00:00:00Z
A production incident case study of Atlassian's 2022 outage, where a maintenance script deleted customer sites and recovery took days.
Spotify | 2022-03-08T00:00:00Z
Explore Spotify's March 2022 outage: Traffic Director, a gRPC client bug, a DNS discovery fallback, and practical checks for an independent recovery path.
Roblox | 2021-10-28T00:00:00Z
A case study of the Roblox 2021 outage, where service discovery and Consul cluster issues contributed to a long recovery.
Facebook | 2021-10-04T00:00:00Z
A root cause analysis of Facebook's October 2021 outage, covering BGP route withdrawal, DNS failure, and operational recovery complexity.
Fastly | 2021-06-08T00:00:00Z
A production incident case study of Fastly's 2021 CDN outage, where a latent software bug was triggered by customer configuration.
Slack | 2021-01-04T00:00:00Z
A practical case study of Slack's January 2021 outage, focusing on capacity, dependency recovery, and customer-facing degradation.
Google | 2020-12-14T00:00:00Z
Learn how Google's December 2020 authentication outage followed a quota automation failure, why stale identity data mattered, and what engineers can practice.
AWS | 2020-11-25T00:00:00Z
Explore the November 2020 AWS Kinesis outage: a fleet expansion exposed a thread limit, routing failed, and recovery required careful control of cold starts.
Cloudflare | 2019-07-02T00:00:00Z
A production incident case study on Cloudflare's 2019 WAF outage, where a rule change caused CPU exhaustion at the edge.
Google Cloud | Sun Jun 02 2019 00:00:00 GMT+0000 (Coordinated Universal Time)
A concise incident analysis of the Google Cloud 2019 outage, where a configuration change caused network congestion and broad service impact.
GitHub | 2018-10-21T00:00:00Z
GitHub's October 21, 2018 outage explained: how a network partition and MySQL failover created data-consistency risks, plus recovery decisions and lessons.
Azure DevOps | 2018-09-04T00:00:00Z
A practical root cause analysis of the Azure DevOps 2018 outage, including regional dependency failure, recovery gaps, and reliability lessons.
GitHub | 2018-02-28T00:00:00Z
How GitHub handled its February 2018 DDoS attack: network saturation, traffic diversion, recovery checks, and a practical exercise in availability response.
AWS | 2017-02-28T00:00:00Z
A concise root cause analysis of the AWS S3 2017 outage, its impact, remediation, and reliability lessons for production engineers.
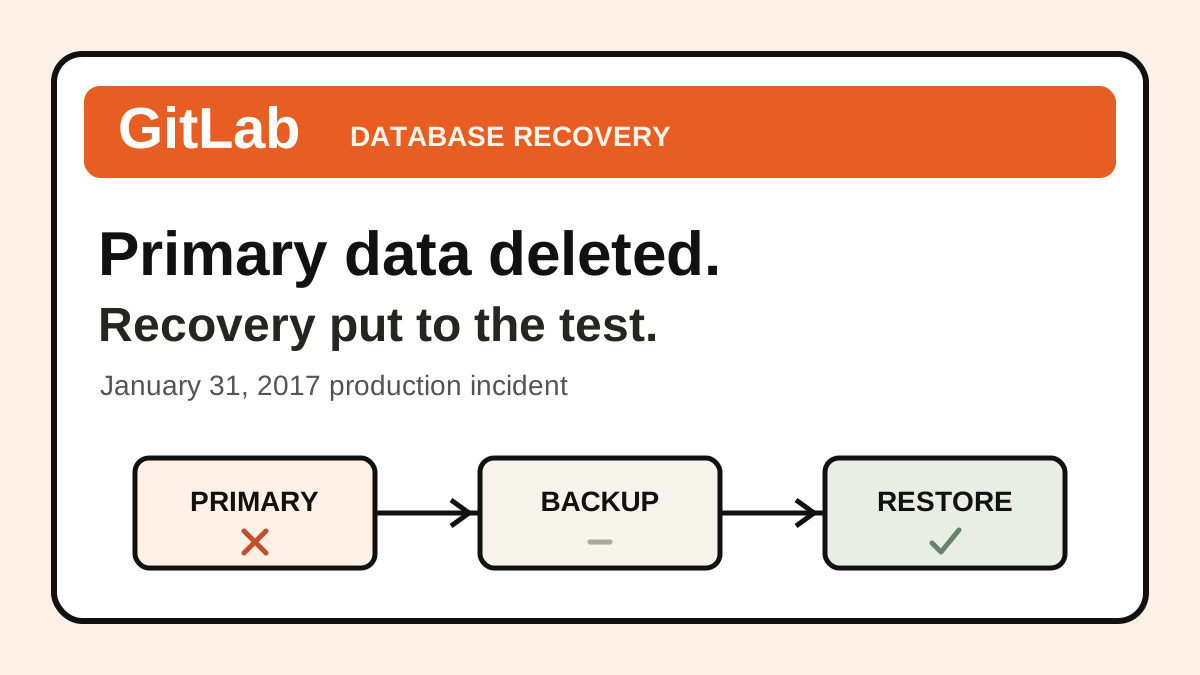
GitLab | 2017-01-31T00:00:00Z
What caused GitLab's 2017 database outage? Explore the accidental deletion, failed backup assumptions, recovery limits, and a practical restore exercise.
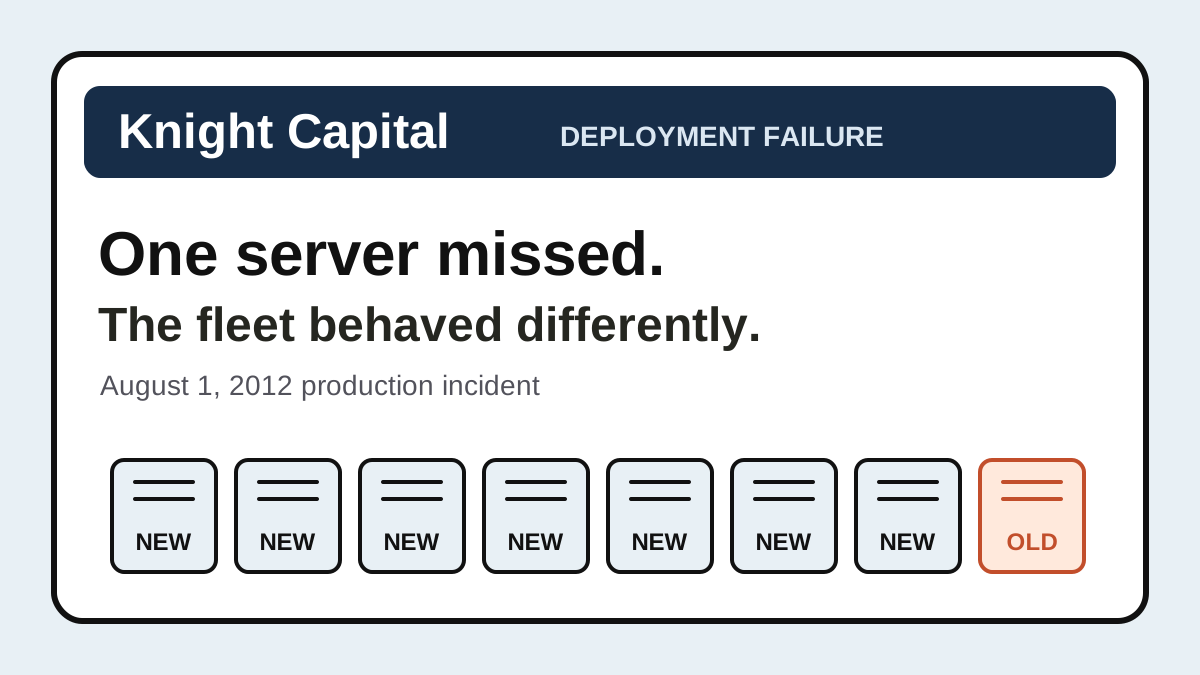
Knight Capital | 2012-08-01T00:00:00Z
Understand Knight Capital's 2012 deployment failure: one inconsistent server, dormant code, unsafe rollback, and the need to verify fleet behavior and limits.
How do I find what change caused a production outage?
Start with the first known failure and compare it with recent changes. A nearby deploy is a lead, not proof of the cause. Include configuration, feature flags, infrastructure, and data changes in the investigation.
- Establish the timeline. Align the first errors, affected requests, and change events using the same time zone.
- Compare affected and healthy systems. Look for differences in versions, configuration, regions, and dependencies.
- Test a specific hypothesis. Predict which requests should fail if a candidate change is responsible, then check the evidence.
- Verify recovery. Check customer behavior and data correctness after mitigation, not just whether an alert clears.
The GitHub MySQL incident shows why restoring connectivity does not automatically restore correct database state. For a repeatable investigation method, see Google SRE's troubleshooting guide.
What is a production incident?
A production incident is a failure or degradation that affects people using a live service. These case studies explain the impact, cause, and recovery decisions, so you can compare failure patterns across systems.
How can I practice investigating an incident?
Start with our SRE incident response game guide. In The Incident Challenge, you investigate a fictional failure, apply a runtime configuration fix, and validate it with a deploy. The aim is to prove that the system works again.